Figure 1: VAlue STitching (VAST)
Figure 1: VAlue STitching (VAST)
VAST compositionally stitches cumulative returns between adaptive-length, actionable sub-goals. (Left): an auxiliary G-function measures the expected discounted return between two reachable states over a specific horizon \(k\), and a stitching policy \(\pi_\text{stitch}\) selects the horizon \(k^\star\) and sub-goal jointly. (Right): among all reachable \((k, s_k)\), the value target \(G(s,s_k,k)+\gamma^k V(s_k)\) is taken at the optimal one, giving horizon-adaptive value supervision.
The quintessence of RL lies in value. However, conventional temporal-difference (TD) learning suffers from value-estimation bias that accumulates over the horizon, while extended-horizon methods, such as \(n\)-step TD backups and Q-chunking, adopt a rigid, fixed-horizon recipe that is often not flexible enough to capture complex value structures in long-horizon, multi-stage tasks.
Human decision-making adapts credit assignment to the task horizon. For distant objectives, humans conceptualize coarse sub-goals with a rough horizon estimate (e.g., walk straight for about 100 m, then turn right); for immediate, critical decisions, they focus on proximal, actionable consequences (e.g., decelerate and move left to avoid an obstacle). Truly adaptive, practically deployable mixed-horizon offline RL remains largely underexplored.
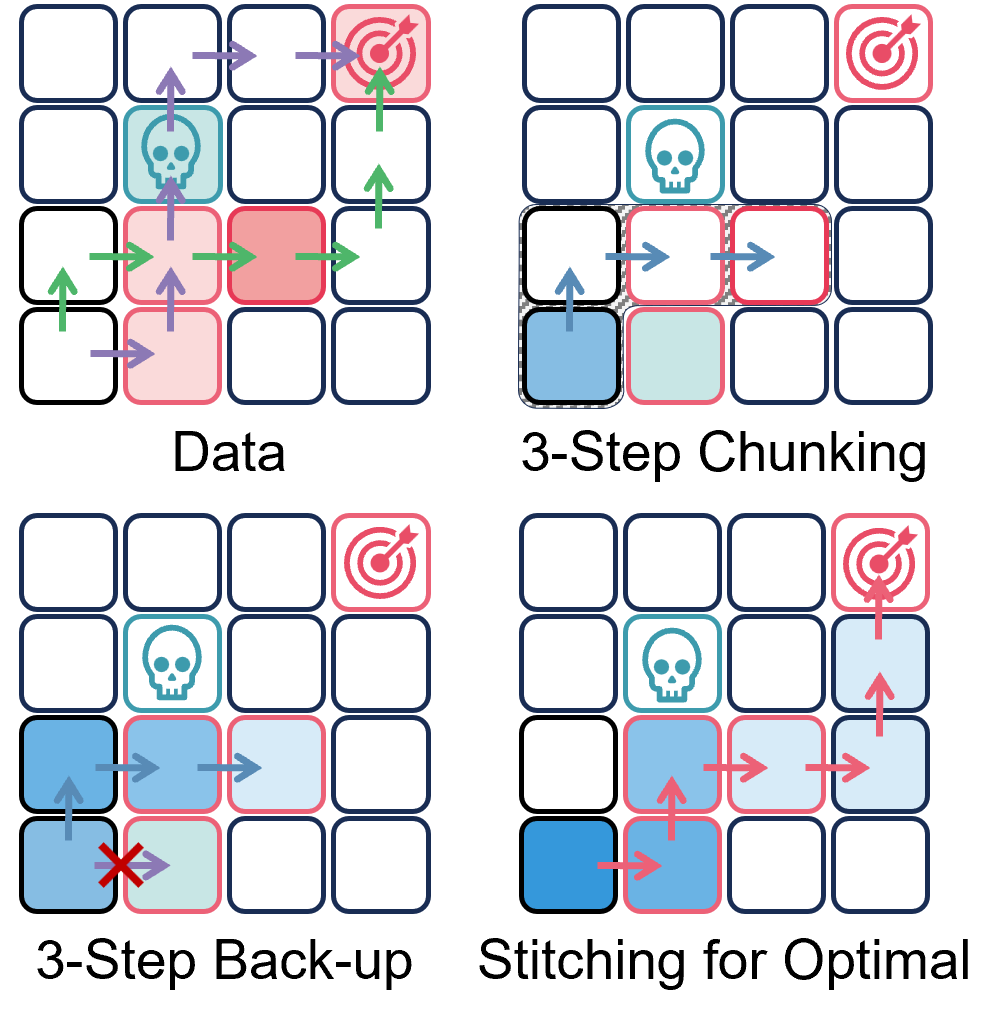
Figure 2: 4×4 grid navigation.
Central to the identified problem of fixed-horizon value-learning is that, while it may yield more robust value estimates, it is poorly suited to extracting policies for real-time, stepwise execution. When the backup sequence length is mismatched, crucial single-step signals can be washed out by sequence-level averaging, leading to the loss of precisely the information needed for accurate immediate decisions. Toy example (Figure 2) requiring navigation from the bottom-left to the top-right. The data include sub-optimal paths only (green path and purple path); the environment is specified by dark red, light red, and skull blocks, indicating high-, low-, and punitive-reward. The depth of blue in blocks indicates the value estimates from fixed-step/chunked value backups, and the optimal stitching value.
Although deliberately simple, this toy example can be viewed as a local subproblem embedded within a much larger maze. It shows that while coupling value updates to a fixed horizon can better stabilize long-horizon learning scenarios, it simultaneously obscures critical short-range decisions, thereby trapping learning in poor local optima. Stability should not be bought at the cost of erasing decisive short-term signals, motivating adaptive horizon modeling that preserves both robustness and flexibility. Therefore:
The selection should be efficient, effective, adaptive, and optimal.
This calls for a more general operator that can evaluate the cumulative return between any pair of states under a dynamically chosen horizon, rather than value estimates tied to fixed transition segments in the buffer.
With the definition of G, the state value admits a horizon-mixed form
$$V^\pi(s) = \mathbb{E}_{k\sim\mathrm{Unif}\{1,\dots,K\},\,s_k\sim\Gamma^\pi(s,k)}\big[G(s,s_k,k)+\gamma^k V^\pi(s_k)\big],$$which recovers the standard Bellman equation at \(k=1\). To inject G into the backup process, we naturally further introduce the stitching Bellman operator.
The stitching Bellman operator offers a new way to bootstrap the value estimates based on the optimal horizon lengths and target states. Together, there needs to be a stitching policy that simultaneously selects the best horizon \(k\) for value stitching and the reward-maximizing sub-goal. We have the following objectives:
$$\mathcal{L}_V = \mathbb{E}_{s \sim \mathcal{D},\,(k, s_k) \sim \pi_\text{stitch}(\cdot\mid s)} \Big[ L_{2}^{\tau}\big(\underbrace{G(s,s_k,k)+\gamma^k V(s_k)}_{V^\pi_\text{target}} - V(s)\big) \Big], \quad L_2^\tau(u)=|\tau-\mathbb{I}(u<0)|\,u^2$$ $$\mathcal{L}_{\pi_\text{stitch}} = \mathbb{E}_{(s,k,s_k)\sim\mathcal{D}}\Big[ \exp\big(\beta\,(V^{\mathcal{D}}_\text{target} - V(s))\big)\,\log \pi_\text{stitch}(k,s_k\mid s) \Big]$$Action extraction. A goal-conditioned flow policy \(\pi_\text{exec}(a\mid s,s^+)\) is trained by imitation on in-trajectory future states. At test time, \(\pi_\text{stitch}\) outputs a horizon–sub-goal pair \((k, s_k)\); \(\pi_\text{exec}\) is conditioned on the sub-goal \(s_k\), and actions are filtered by rejection sampling:
$$a^\star = \arg\max_{a \in \{a^{(1)}, \ldots, a^{(N_\text{rej})}\} \sim \pi_\text{exec}(\cdot \mid s, s_k)} Q(s,a),\qquad (k, s_k)\sim\pi_\text{stitch}(\cdot\mid s).$$
VAST is evaluated on the state-based singletask variant of OGBench: 30 tasks in 6 Basic domains and
20 tasks in 4 Hard domains with higher planning complexity, 50 tasks in total.
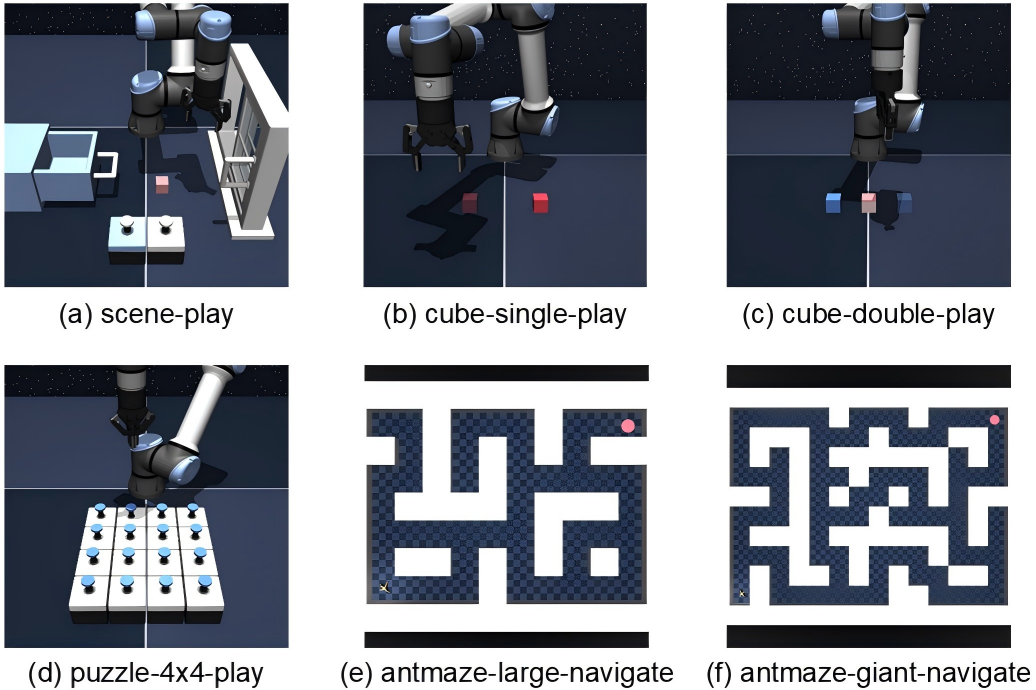
Figure 3: OGBench Basic.
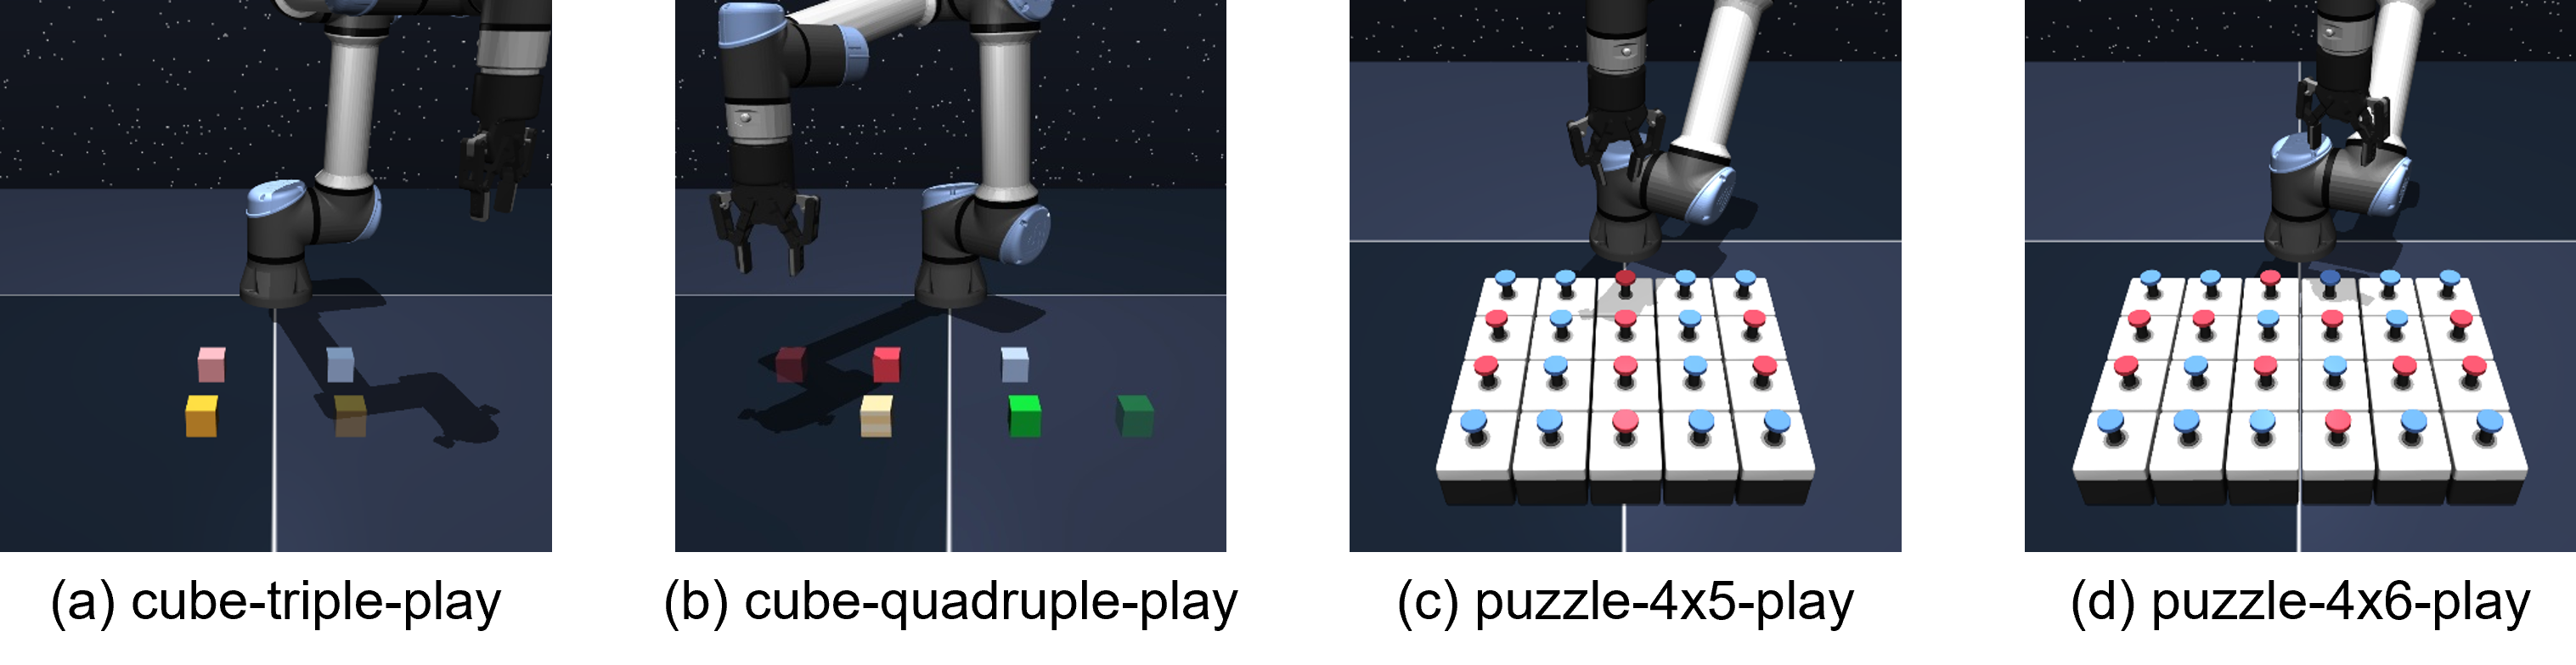
Figure 4: OGBench Hard.
VAST achieves the best overall score on both Basic and Hard, with pronounced gains on manipulation domains.
Table 1: OGBench Results. Success rate at 1M steps, over 8 random seeds.
Offline learning curves on cube-double-play (top) and puzzle-4x4-play (bottom).
VAST consistently outperforms competing methods on most tasks.

Figure 5: Learning curves. (Top): cube-double-play. (Bottom): puzzle-4x4-play.
We scale the batch size and layer width of VAST on cube-triple-play. Increasing either yields a clear performance scaling trend,
and at the larger settings VAST achieves its best results, indicating strong scaling potential.

Figure 6: Performance on cube-triple-play.
The blue dashed line marks the best baseline on each task.
We visualize the ground-truth trajectory together with the sub-goals predicted by \(\pi_\text{stitch}\). The predicted horizons follow a plausible sequence of phased atomic intentions: the policy selects effective intermediate targets and progresses toward stable, value-maximizing actions.
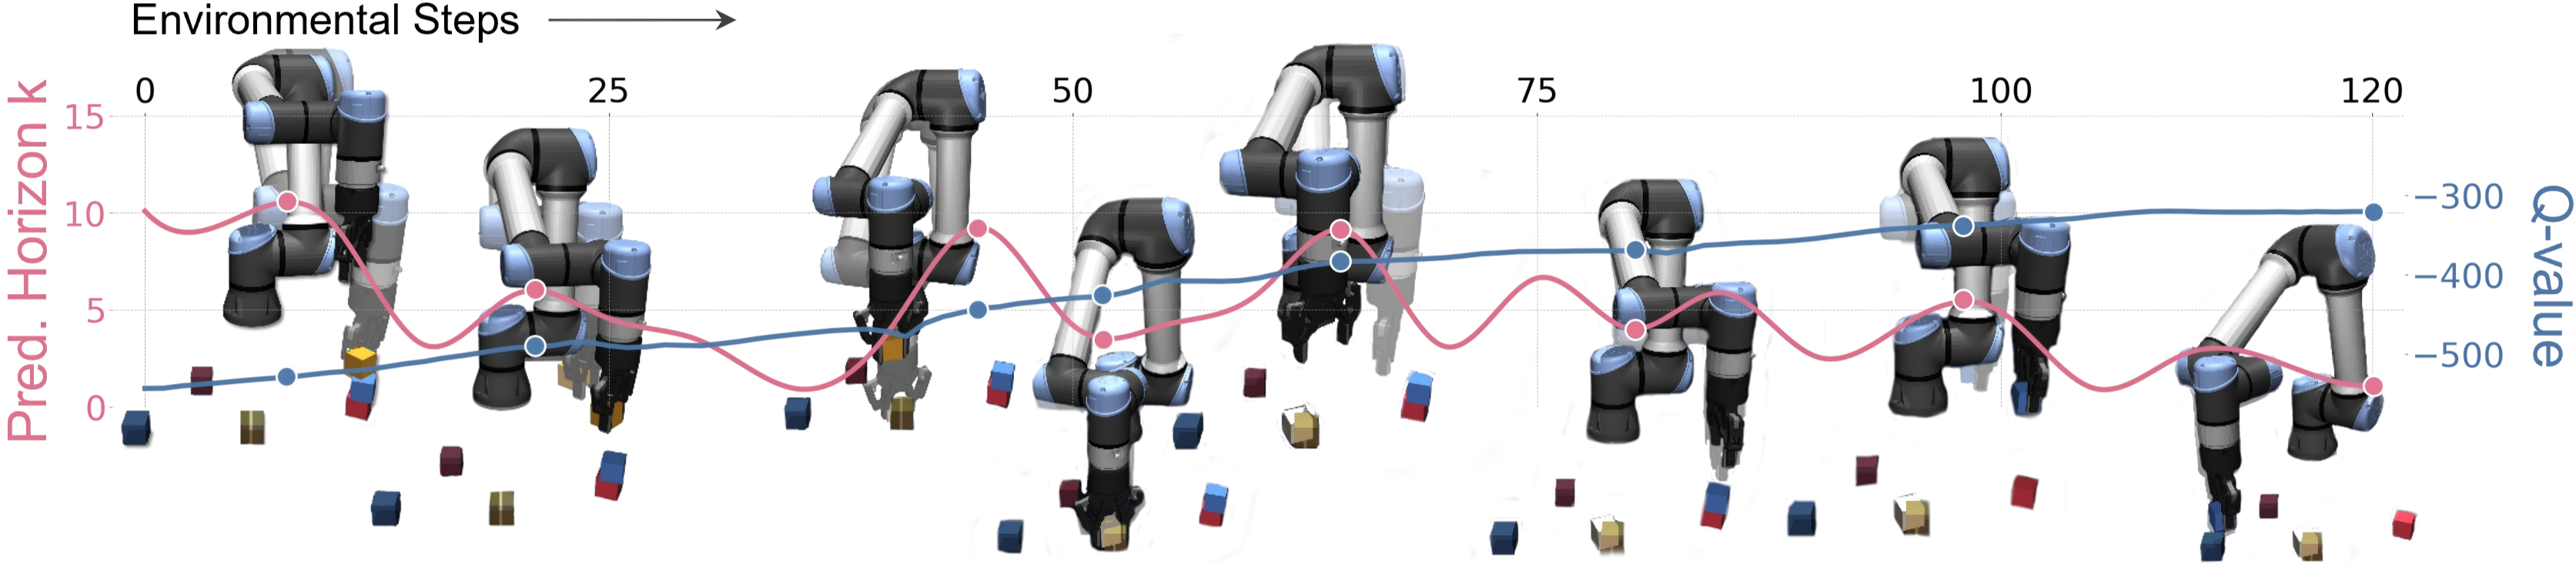
Figure 7: cube-triple-play-task3 (pop_from_stuck). Solid arm: current pose; transparent arm: predicted sub-goal.
@inproceedings{zheng2026vast,
  title     = {Horizon Adaptive Offline Policy Learning via Value Stitching},
  author    = {Kexin Zheng and Xianyuan Zhan and Xintao Yan},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026}
}